Chapter 12: Settings, Plans and FAQ
Common settings (language, backup, model location, API keys), the differences between the Free and Pro plans, signing in and licensing, and answers to common questions.
Chapter 12: Settings, Plans and FAQ
12.1 Common settings
Click Settings in the left menu (the gear icon). There's a Search settings... box at the top left. If you can't find an option, typing a keyword there is the quickest way.
General
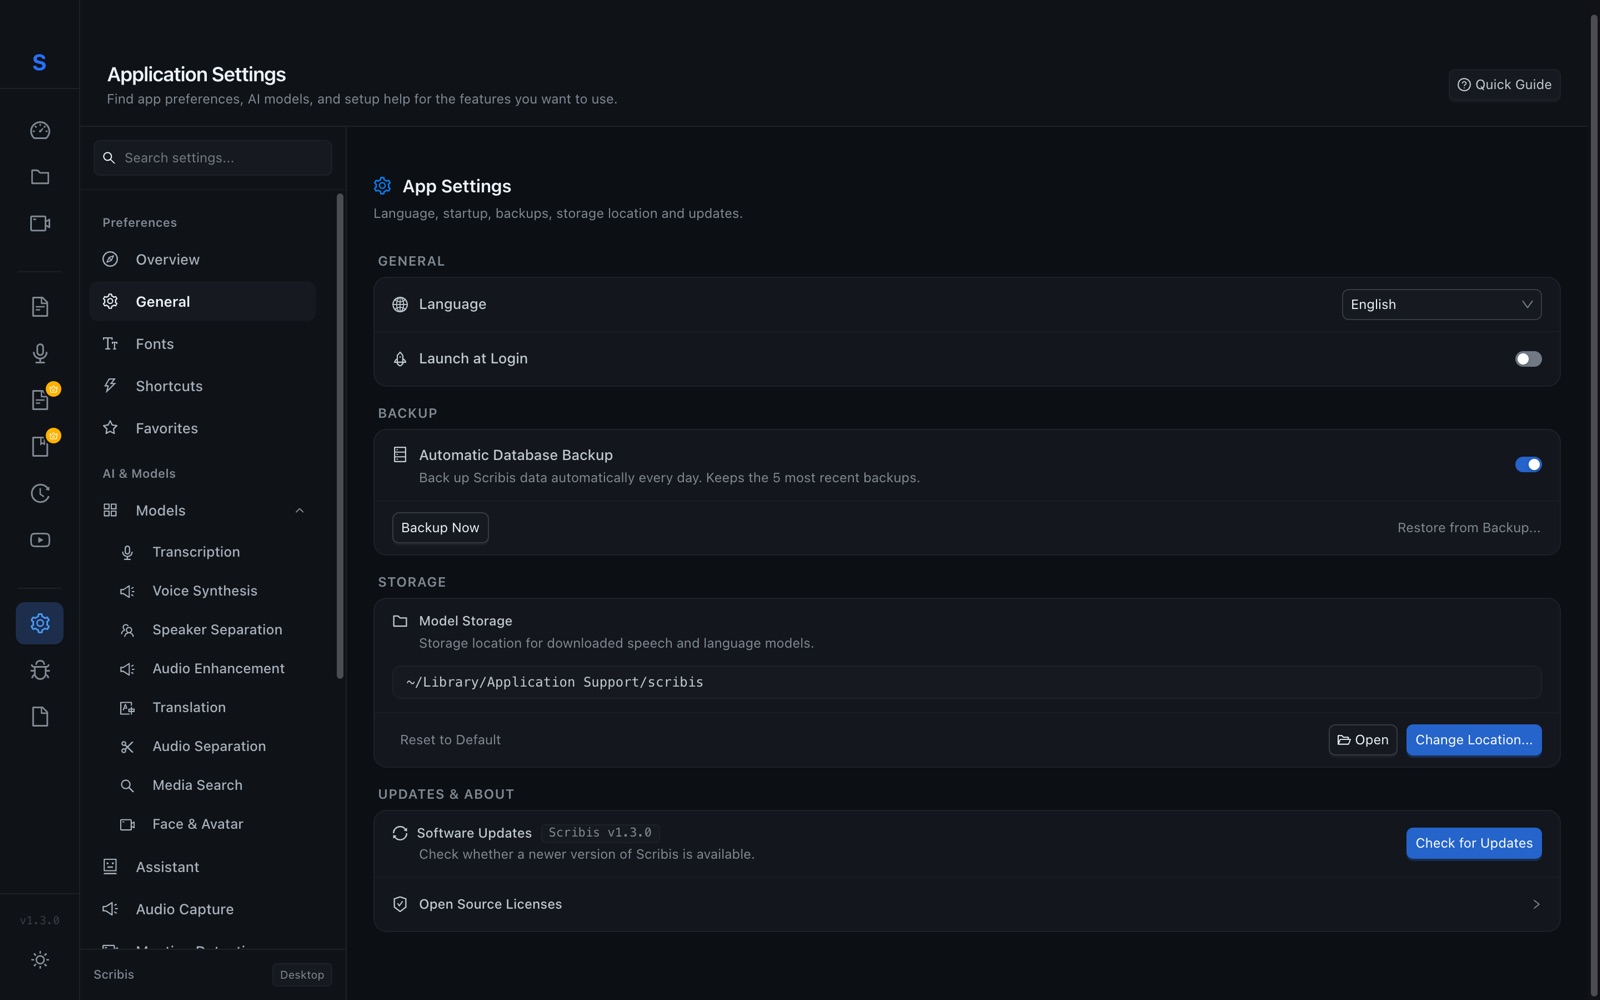
- Language: change the app's language (English, 繁體中文 and more).
- Launch at Login: opens Scribis when your computer starts, so recording shortcuts are always ready.
- Automatic Database Backup: backs up your Scribis data every day and keeps the 5 most recent copies. You can also click Backup Now to back up by hand.
- ⚠️ Restore from Backup... replaces your current data with the data from that backup, so anything added after the backup may disappear. Before restoring, click Backup Now to save a copy of your current data.
- Model Storage: where models are saved. Running low on space? Click Change Location... to move them to an external drive.
- Software Updates: click Check for Updates to get the latest version.
💡 Dark / light mode: click the sun icon at the very bottom of the left menu.
API Keys (only needed for cloud AI)
If you want to use cloud services such as Gemini or OpenAI for transcription, translation or summaries, you need an API key (a private code that lets Scribis use that service on your behalf; you get it from the service's website. See Chapter 6, section 6.1 for how). If you only use local models, skip this part.
- Go to Settings › API Keys.
- Click Connect next to the service you want (for example Google Gemini).
- Paste the API key you got from that service's website and save it. A green Configured label means you're done.
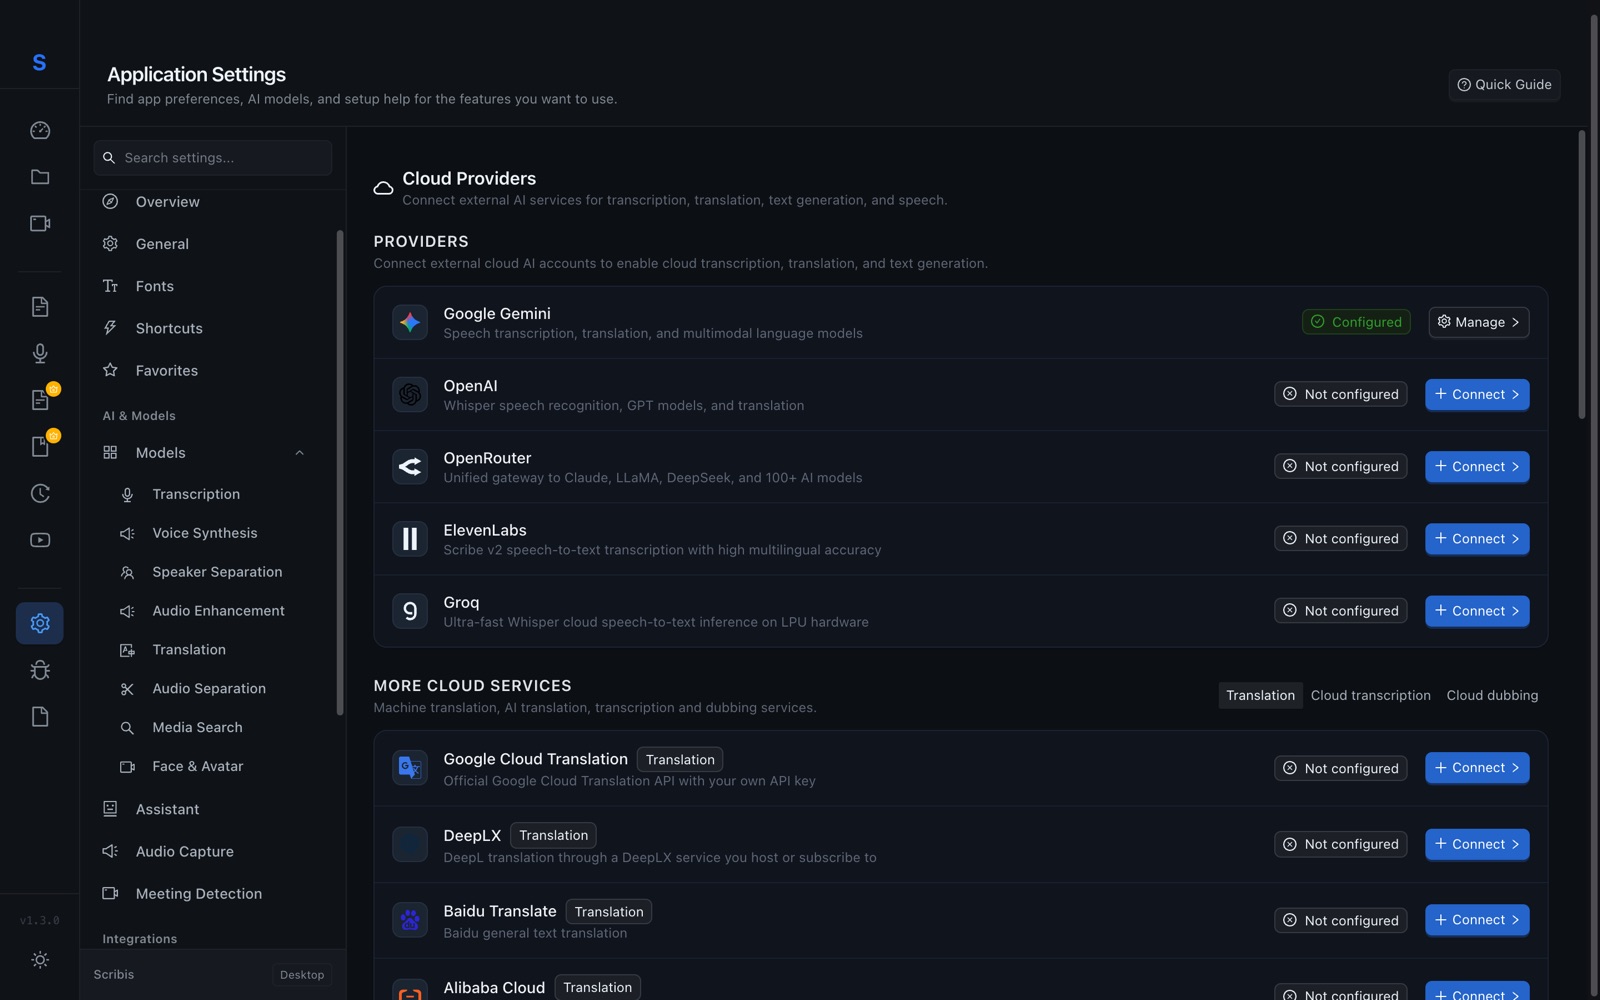
🔒 Keys are encrypted and stored on your computer. If you only use local models, you don't need any API keys.
Every item on the Settings page
Except for API keys, which you paste in and then click Save Key, settings save automatically; there's no Save button. Below is every item in the order of the left menu. Some items only appear on certain computers or with Pro, as noted in the last column.
Preferences
| Item | What it's for | Notes |
|---|---|---|
| Overview | Checks whether you're ready to transcribe; the quick setup steps walk you through downloading anything that's missing | Start here the first time |
| General | Interface language, launch at login, backup and restore, where models are stored, checking for updates | See above |
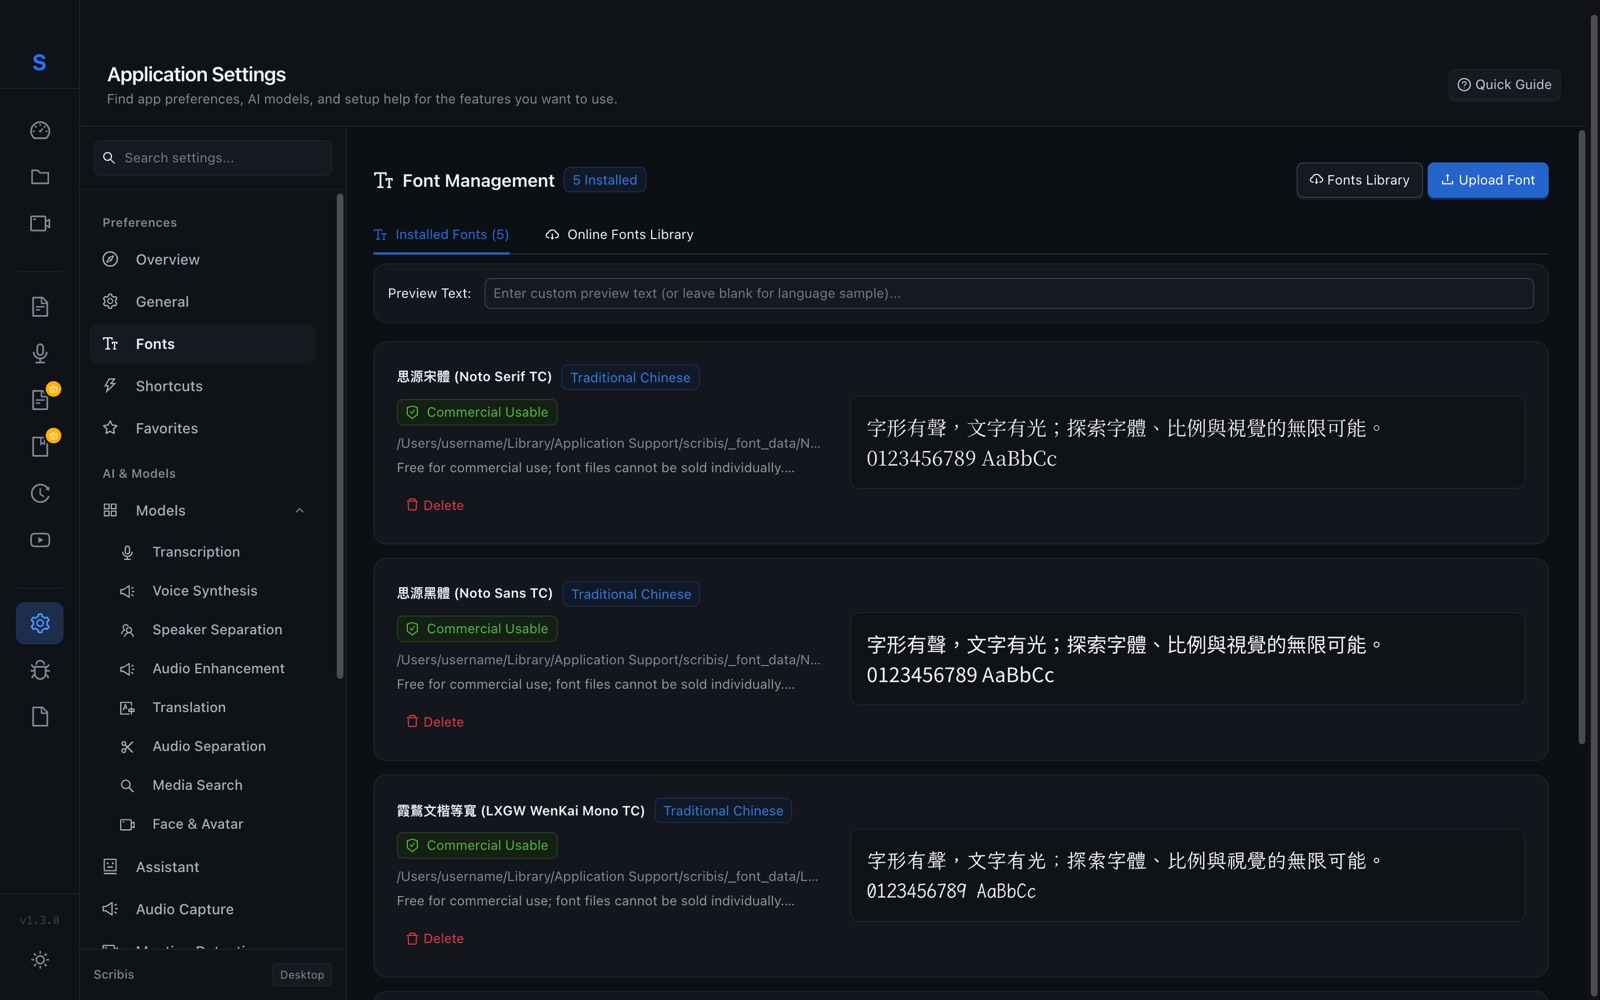
| Fonts | Manages the fonts used for subtitles: Online Fonts Library downloads free fonts, Upload Font adds your own font file | Check the "Commercial Usable" tag before commercial use |
| Shortcuts | Changes the global shortcuts for recording and the AI Assistant | See Chapter 5 |
| Favorites | Keeps the models and voices you use most. Menus on other pages only show models you've marked as favorites; if you downloaded a model but can't find it, come here or click its star on the Transcription page |
AI & Models › Models
| Item | What it's for | Notes |
|---|---|---|
| Transcription | Downloads speech-to-text models and sets the Default ASR Model | See Chapter 3 |
| Voice Synthesis | Downloads AI voice-over engines and voices (Kokoro, Qwen3 TTS, VoxCPM2, Apple voices and more); click Test Voice to listen | Audio Watermark adds an inaudible mark to voice-overs |
| Speaker Separation | Downloads the model used by Speaker Diarization to tell who is speaking. It's different from Audio Separation below, which removes background music. Nemotron-3 is recommended (about 107 MB; it's just the model's name, you don't need to understand it) | Pro |
| Audio Enhancement | Downloads the denoiser that makes noisy recordings clearer | Pro |
| Translation | Apple Intelligence, macOS translation, local translation models, and the General LLM Models used for AI chat and summaries | Cloud translation is set up under API Keys |
| Audio Separation | Downloads the model that separates voices from background music (about 84 MB) | |
| Media Search | Downloads the smart search model (about 820 MB) so you can search the Media Library with a sentence | After downloading, build the index under Experimental › Search Index |
| Face & Avatar | Downloads the files needed for Face Mosaic and the Talking Avatar (the same files as Experimental › Face Mosaic; install in either place) | You must accept the license first |
| Document OCR | Downloads the OCR text recognition model | Windows only |
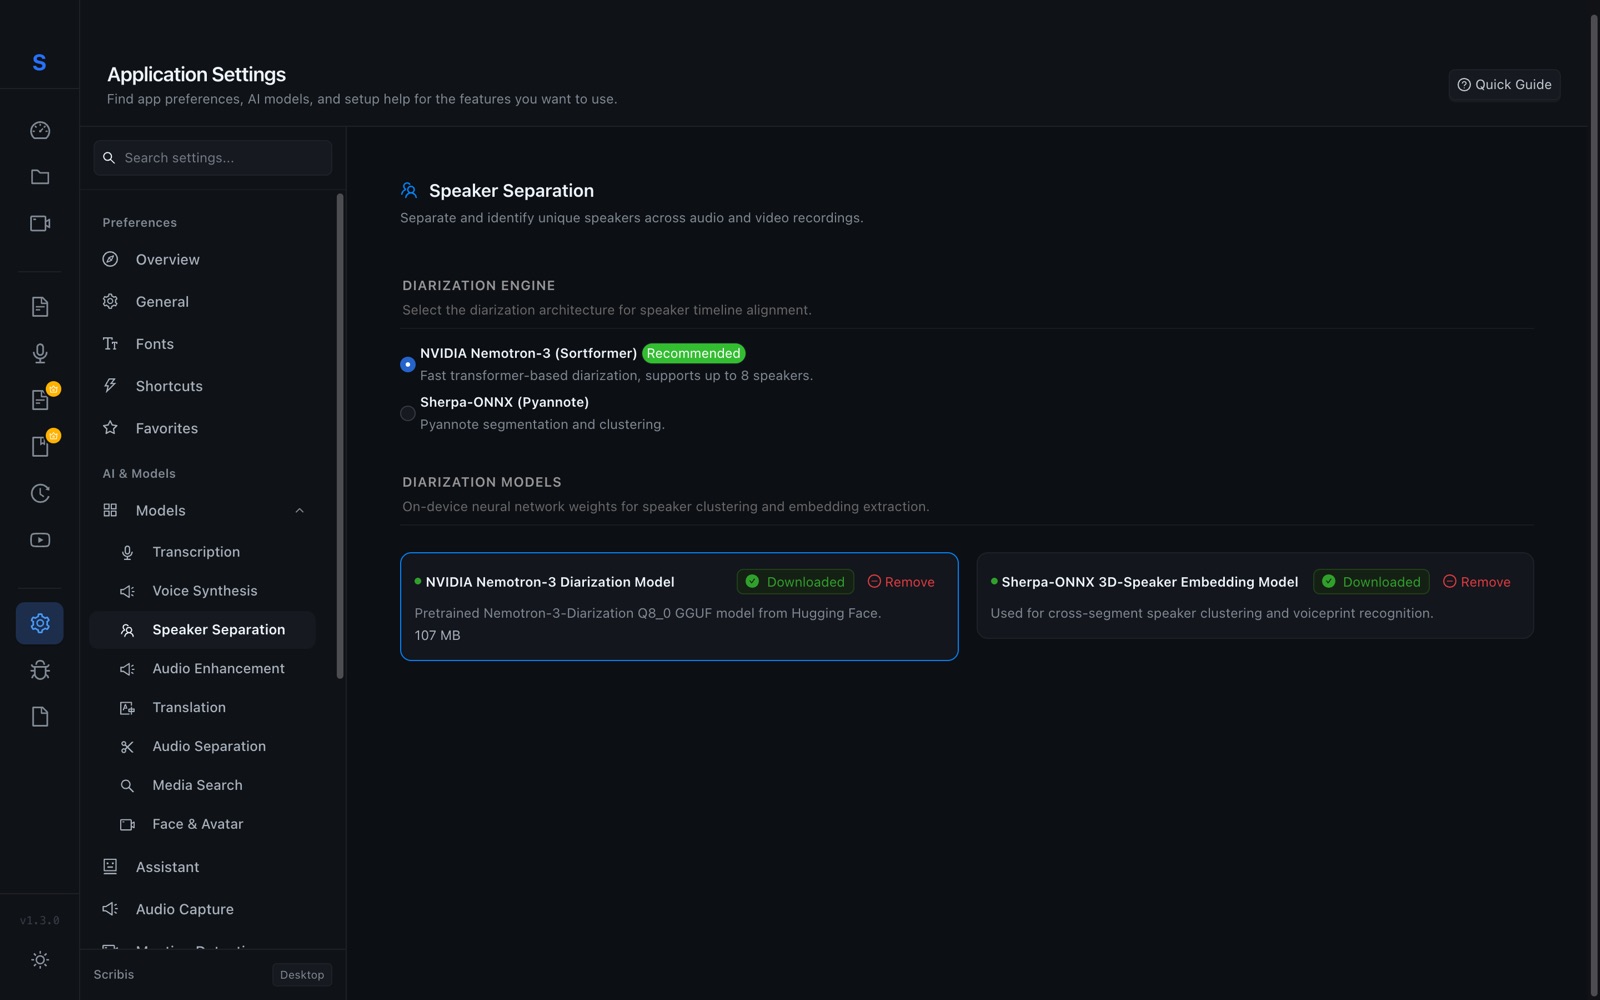
AI & Models › other items
| Item | What it's for | Notes |
|---|---|---|
| Assistant | Settings for voice typing and AI rewriting (language, model, auto-paste, history) | See Chapter 5; choosing the cloud AI assistant sends your text to the cloud |
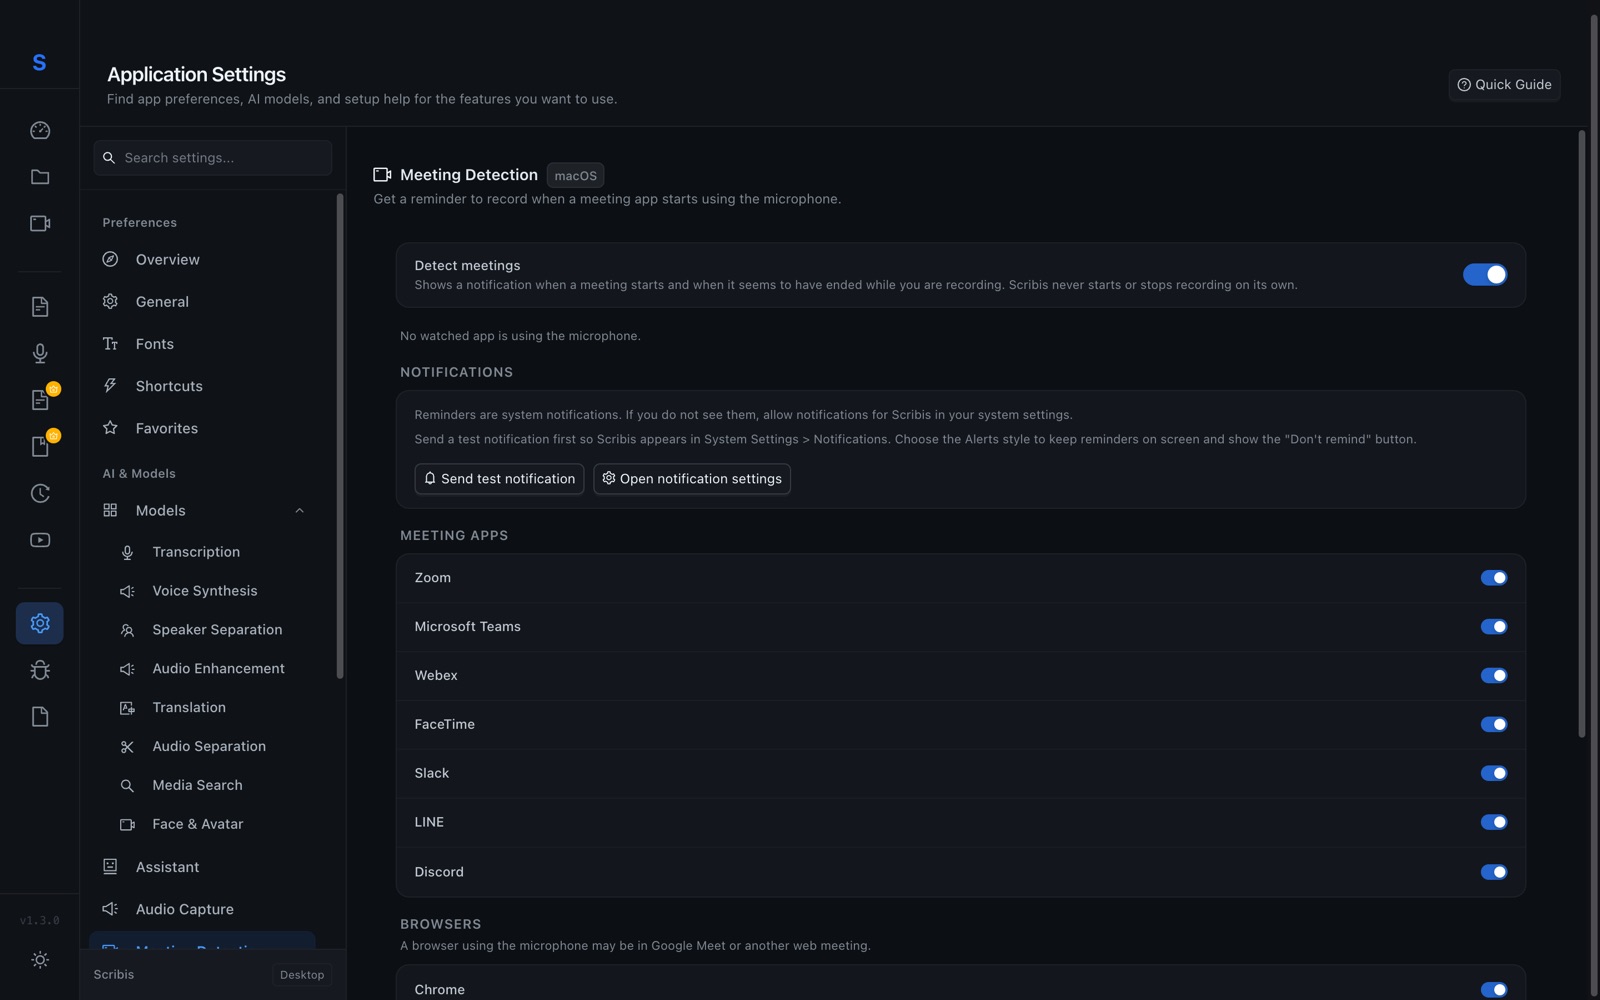
| Audio Capture | When recording computer sound, whether to capture every app or chosen apps, and whether to mix in the microphone | Mac and Windows |
| Meeting Detection | Shows a reminder to record when Zoom, Teams, Google Meet and similar apps start using the microphone | Only reminds you; never starts recording itself. Not in the Mac App Store version |
Integrations
| Item | What it's for | Notes |
|---|---|---|
| API Keys | Connects cloud services such as Gemini and OpenAI | See above |
| MCP | Lets outside AI assistants control Scribis | See Chapter 11 |
System & Tools
| Item | What it's for | Notes |
|---|---|---|
| Hardware | Shows whether your Mac's chip is speeding things up; sets up NVIDIA graphics acceleration on Windows | See Chapter 2 |
| FFmpeg | FFmpeg is a tool that processes video sound and pictures. Most people never need to set it; only if you get an error such as "can't process" when importing or exporting do you need to point Scribis to it here; if you're not sure how, contact us via Bug Track | Not in the Mac App Store version |
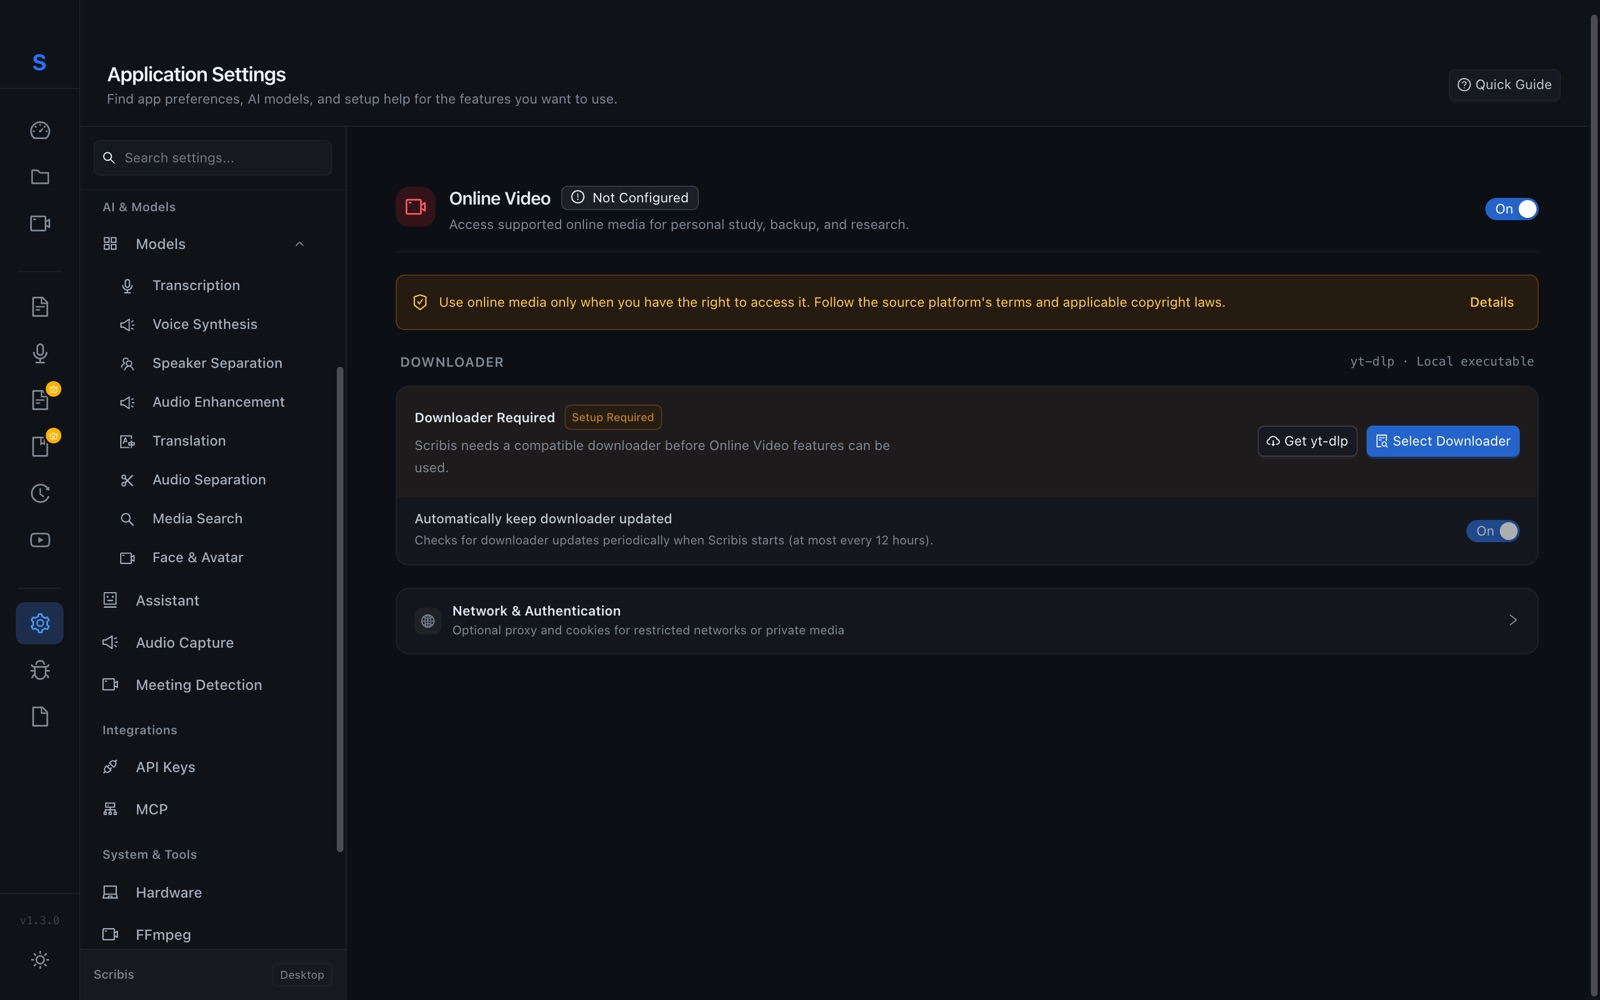
| Online Video | Turns on downloading YouTube and other online videos: click Get yt-dlp (a free download tool) and turn the switch on. Skip the advanced network options unless downloads keep failing | Not in the Mac App Store version; only download content you have the right to use |
| Experimental | Features still being tested, which may sometimes make mistakes (see the table below) | |
| About | Version, website, privacy policy and contact details; Copy System Info is handy when reporting a problem |
Experimental features
| Item | What it's for |
|---|---|
| Text Correction | After transcribing, automatically fixes names of companies, people and other special terms (Chinese only for now; needs a model of about 180 MB) |
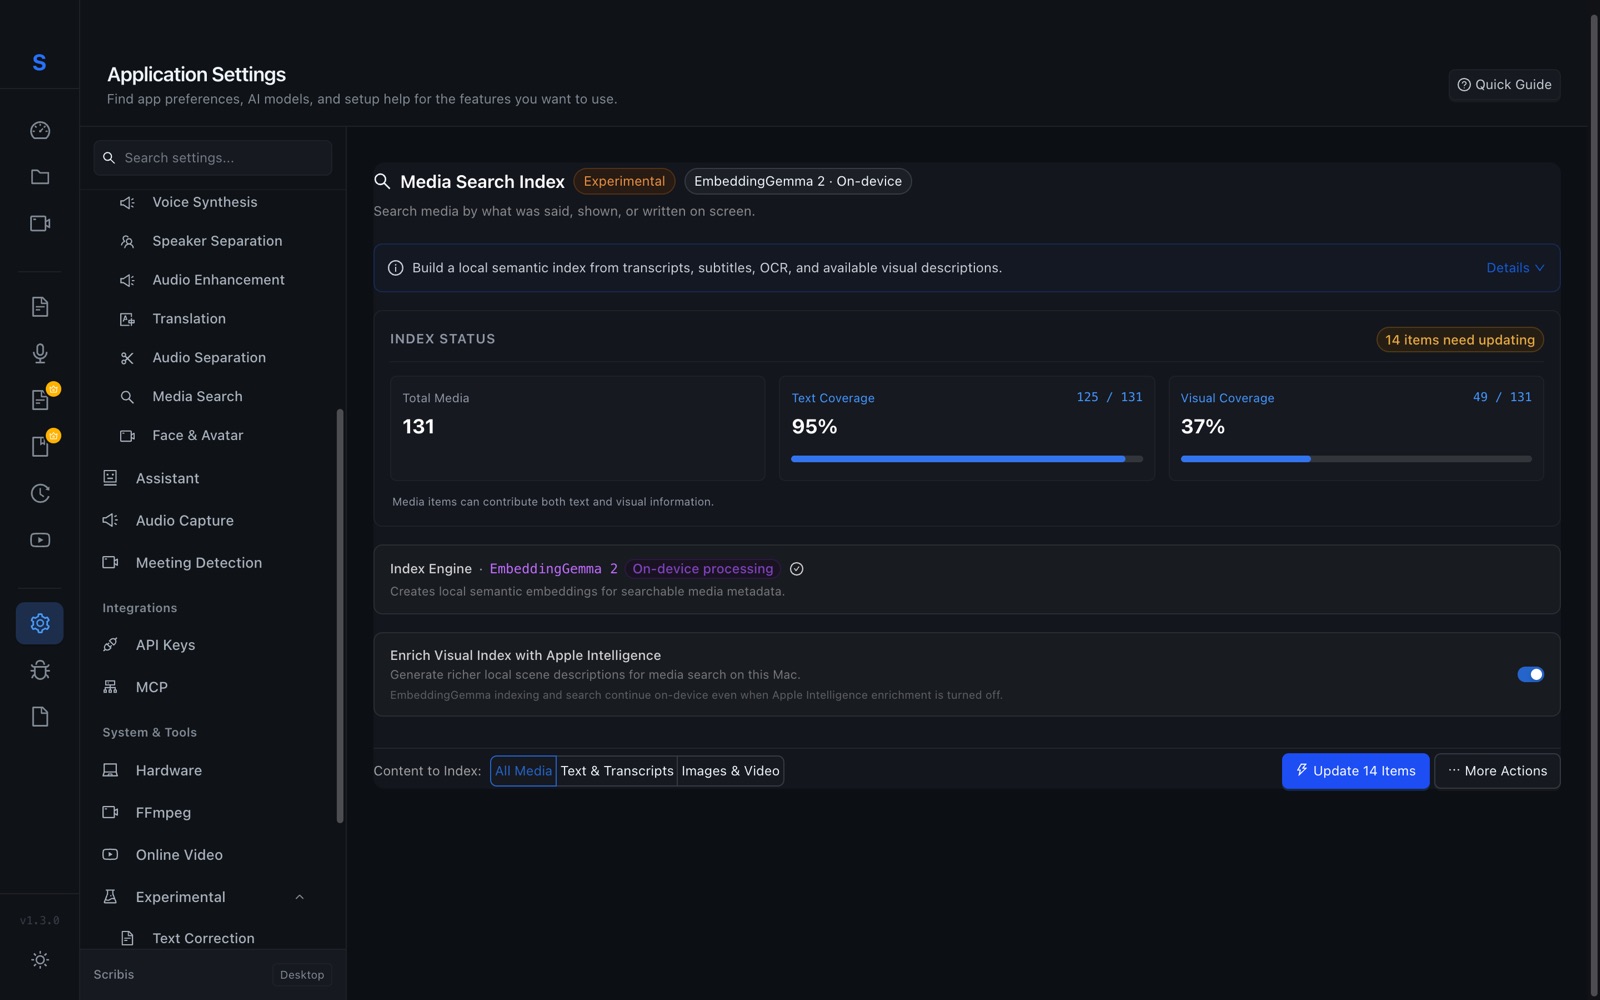
| Search Index | Builds the Media Library's smart search index and shows how much text and video is covered; click Update to process new files |
| Face Mosaic | Installs the face detection engine used by Auto Mosaic in the Timeline Editor |
| Talking Avatar | Makes a talking avatar video from one portrait photo and a voice recording (needs a powerful computer) |
| Voice Design | Designs a new voice from a text description, or copies the voice in a recording for AI voice-over (get the person's permission first) |
Where to find other common settings
| What you want to do | Where to go |
|---|---|
| Download or delete transcription models | Settings › Models › Transcription |
| Download local translation or AI models | Settings › Models › Translation |
| Download voices for AI voice-over | Settings › Models › Voice Synthesis |
| Change shortcuts | Settings › Shortcuts (see Chapter 5) |
| Turn on graphics card acceleration | Settings › Hardware (see Chapter 2) |
| Connect another AI assistant | Settings › MCP (see Chapter 11) |
12.2 Free vs. Pro
| Feature | Free | Pro |
|---|---|---|
| Uploaded file you transcribe | Up to 30 minutes each | No limit |
| Live recording (Record page or Mini Recorder) | Up to 10 minutes each | No limit |
| YouTube AI (Chapter 8) | 10 new videos a month | No limit |
| Subtitle editing, translation, export | ✅ | ✅ |
| AI chat and summaries | ✅ | ✅ |
| Batch Transcribe page (sidebar) | — | ✅ |
| Batch Split & Transcribe tab in Single Transcribe | ✅ | ✅ |
| Lexicons & Voiceprints | — | ✅ |
| Speaker Diarization (labels who is speaking), Semantic Source Grouping (AI splits subtitles by meaning) | — | ✅ |
| Timeline Editor and Scene Editor (cut video) | ✅ | ✅ |
| Synthesize All Speech (AI voice-over for every line), Fixed Dictionary | — | ✅ |
| Advanced models: Speaker Separation (tells who is speaking), Audio Enhancement (makes noisy recordings clearer), and large models such as Whisper small and up, breeze-asr-26, vibevoice and qwen3-asr-1.7b (Free includes Whisper tiny/base, breeze-asr-25-q8_0, SenseVoice, Parakeet and qwen3-asr-0.6b) | — | ✅ |
Features marked with a small crown badge labeled Pro in the app are Pro-only. Clicking one shows an Upgrade Now option.
12.3 Signing in and licensing
My Space, at the bottom of the left menu (the page that opens is titled "My Space & Subscriptions"), is where you manage your account and plan.
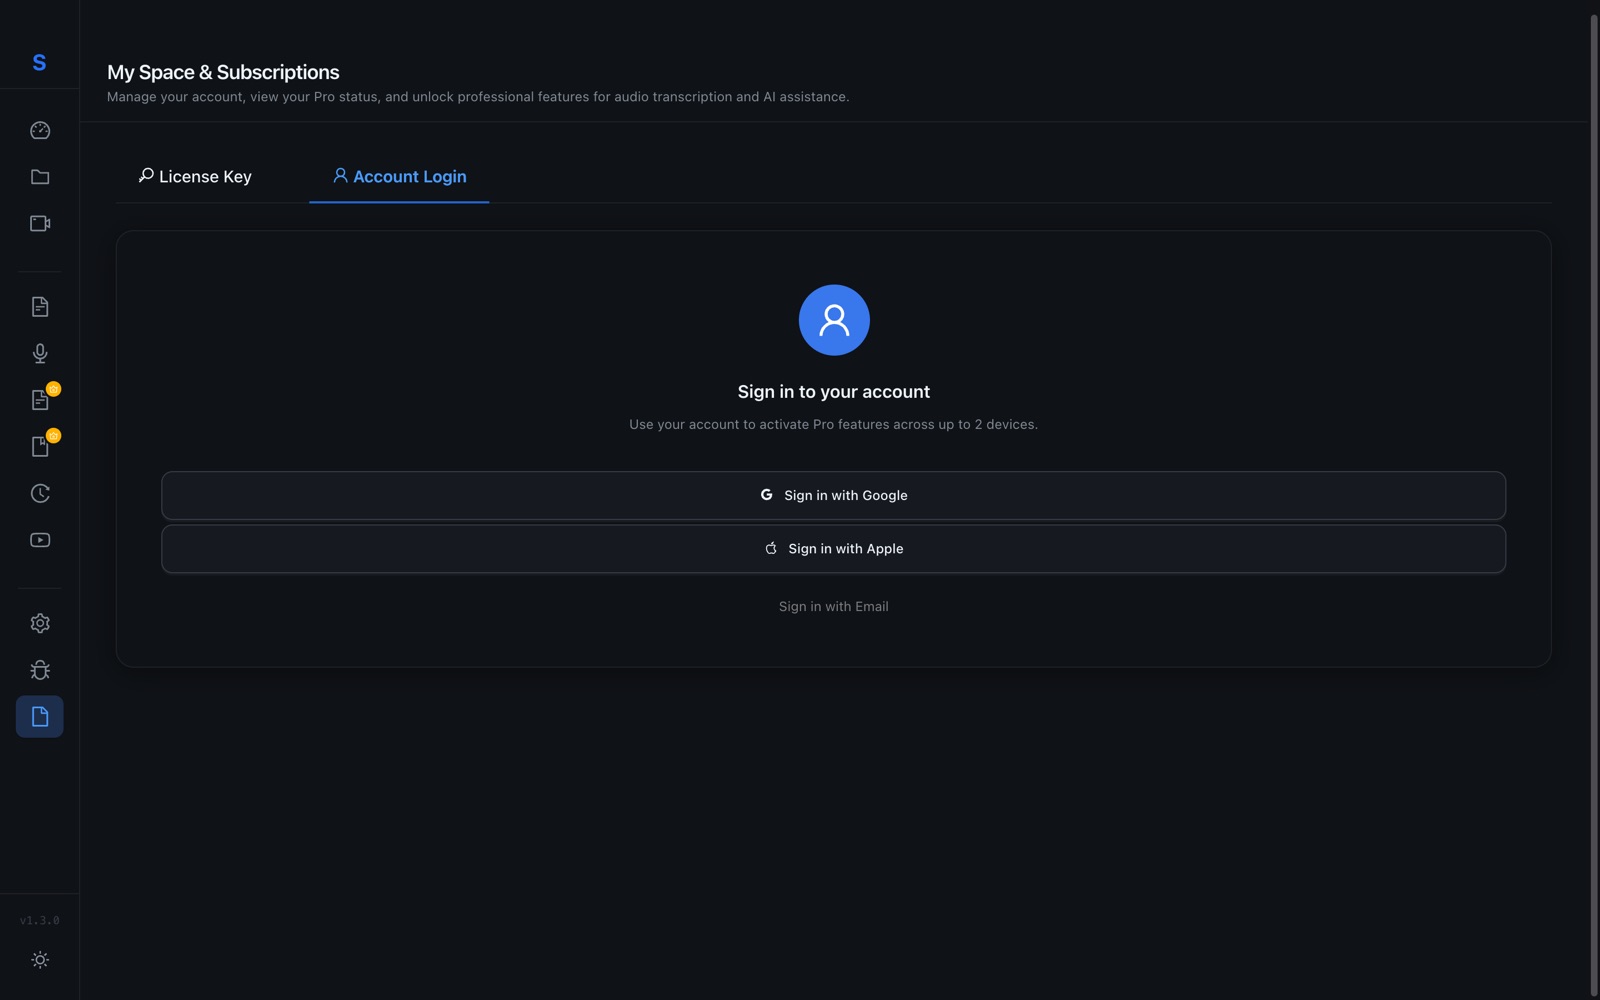
- Account Login: sign in with Google, Apple or email. Once signed in, one account can use Pro features on up to 2 computers.
- License Key: if you bought a license key, enter it on this tab to activate it.
- If you installed Scribis from the Mac App Store, you'll see a Store tab where you can subscribe or buy directly.
💡 Got a new computer? Sign out on the old one first, then sign in on the new one. Each account can be used on up to 2 computers, and after you sign out of the old one, its spot takes about 7 days to free up.
💡 Can I use it offline? Transcription and local models work offline. Pro needs to go online about once every 30 days to check your license. If you'll be offline for a long time (for example traveling abroad), open Scribis while you're still online before you leave and check in My Space that your license status is fine.
12.4 Frequently asked questions
Q1: Will my recordings be uploaded to the internet?
No. With local models, all the processing happens on your computer. Audio, video or text is only sent to a cloud service when you choose to use one (for example by setting up Gemini under API Keys and selecting it).
Q2: The subtitles repeat the same sentence, or show text like "Thanks for watching" when nobody is talking. Why?
Speech models sometimes do this during long silences or background music. To improve it:
- Choose the language instead of using Auto Detect.
- Briefly describe the content in the Prompt under Advanced Settings.
- Try another model (for example SenseVoice or Parakeet).
- Delete those lines in the editor.
Q3: The recognition isn't accurate. What can I do?
Try these in order:
- Choose the language instead of using Auto Detect.
- Switch to a better-suited model (see the recommendations in Chapter 3).
- Add names and product names that keep getting misheard as hotwords (ASR Dictionary) (Pro).
- After transcribing, use Optimize in Optimize & Translate to find mistakes.
Q4: Can I use it on a laptop without a dedicated graphics card?
Yes. Choose models marked CPU Fast (fast even without a dedicated graphics card), such as SenseVoice (Chinese, Japanese, Korean and Cantonese) or Parakeet (English and European languages). They run quickly on an ordinary laptop.
Q5: The models take up too much disk space.
Go to Settings › Models › Transcription and click Remove on models you don't use. You can also move models to an external drive under Settings › General › Model Storage.
Q6: How do I stop a transcription halfway?
Click the red Cancel button next to the progress bar.
Q7: How do I report a problem or contact you?
- In the app, click Bug Track in the left menu.
- Or email
[email protected].