Chapter 3: Transcription Settings and Choosing a Model
Every option on the Single Transcribe page, which model to pick for each language, Advanced Settings (Speaker Diarization, hotwords, prompts), and tips for more accurate subtitles.
Chapter 3: Transcription Settings and Choosing a Model
"Transcription" simply means turning speech into text. This chapter explains every option on the Single Transcribe page and how to pick a model.
3.1 The six tabs at the top
| Tab | When to use it |
|---|---|
| Local File | Transcribe a recording or video on your computer (most common; sections 3.2–3.6) |
| Record | Record something with your microphone inside Scribis, then turn it into text |
| Batch Split & Transcribe | Automatically cut one very long file into parts and transcribe each part |
| URL Transcription | Paste an online video link (for example YouTube), download it and transcribe it |
| OCR | Read subtitles that are printed onto the video picture and turn them into editable subtitles |
| Video Record | Play a video and record your own voice-over as you watch, for dubbing or spoken subtitles |
The Quick Guide button at the top right opens step-by-step help for this page at any time. How to use the last five tabs is explained in 3.7 at the end of this chapter.
3.2 Language Settings
- Auto Detect: Scribis works out the language on its own. Good when you're not sure, or when several languages are mixed.
- Choose a language: pick one from the list. If you know the language, always choose it. You'll get more accurate results and fewer strange words.
- Audio extraction only (another option in this box, not a language): just pulls the sound out of the video without turning it into text.
3.3 Choose a model
In Model Settings, tick Use Local Asr. The list below shows the models you can use:
⚠️ The list only shows models that are downloaded AND starred (marked as favorites). If you can't find a model after downloading it, go to Settings › Favorites or Settings › Models › Transcription and click its star.
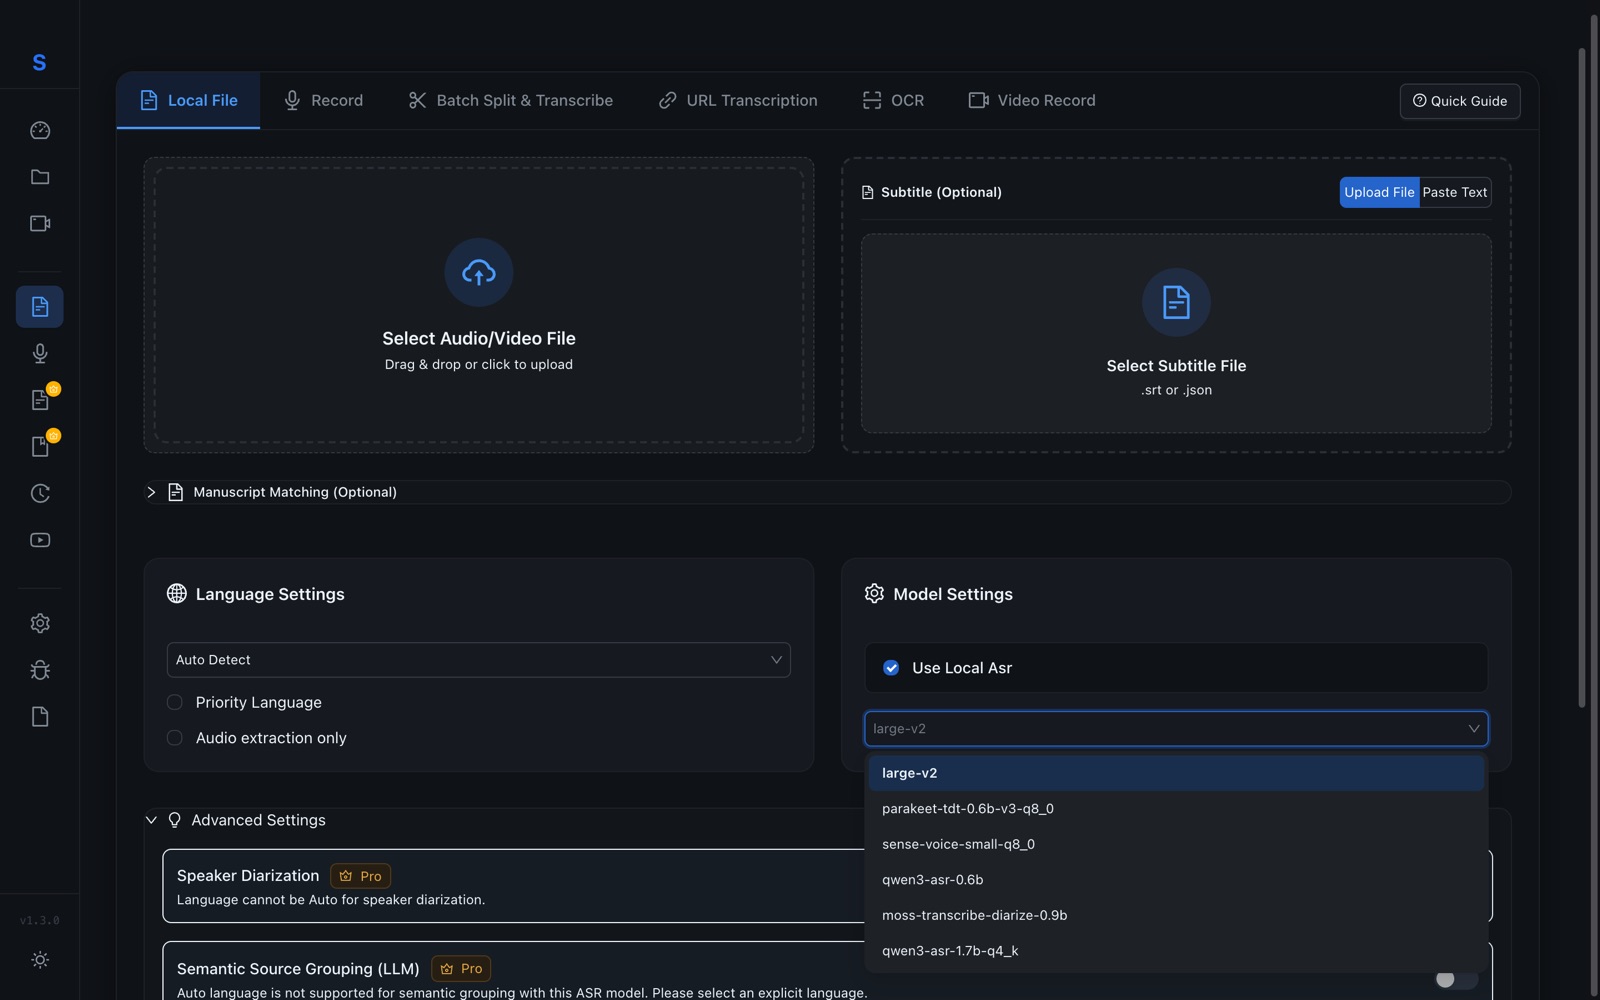
Don't see the model you want? Download it in Settings › Models › Transcription (see Chapter 2).
Which one should I pick?
Don't worry if the model names mean nothing to you. Just go by the "Your situation" column. The easiest option is to use the model recommended the first time you opened Scribis.
| Your situation | Look for this name in the model list | Category in Settings | What it's good at |
|---|---|---|---|
| Not sure | qwen3-asr-0.6b | Recommended | Good in many languages, a balance of speed and accuracy |
| Taiwanese Mandarin, Chinese mixed with English | breeze-asr (breeze-asr-25-q8_0 works on Free; the others are Pro) | Traditional Chinese | Especially familiar with Taiwanese accents and Traditional Chinese |
| Chinese, Cantonese, Japanese, Korean on an older computer | sense-voice | Chinese, Japanese, Korean & Cantonese (shown as CJK + Cantonese) | Very fast, runs smoothly on an ordinary laptop |
| English or European languages | parakeet | English + European (CPU Fast) | Accurate and fast for English, no graphics card needed |
| English, even faster | distil-large-v3 (Pro) | English Fast | Speed first |
| Other languages | Whisper (tiny and base are free; small and up are Pro) | General (Whisper, 99+ languages) | Supports 99+ languages. Bigger is more accurate, but slower and uses more space |
| Long recordings, best quality | vibevoice (Pro) or qwen3-asr-1.7b (Pro) | Advanced | Needs a newer, more powerful computer (for example a recent Apple silicon Mac; if unsure, use the ones above) |
💡 Advanced: use a cloud service instead (you can skip this). Untick Use Local Asr (ASR = speech recognition) to transcribe with an online service (such as Google Gemini or OpenAI). To do this, first get an API key from that service's website (a string of characters that works like a password; don't share it, and some services charge for use), then paste it in Settings › API Keys. Your audio is sent to that company for processing.
3.4 Advanced Settings
Click Advanced Settings to see more options. They're all optional; transcription works fine without them:
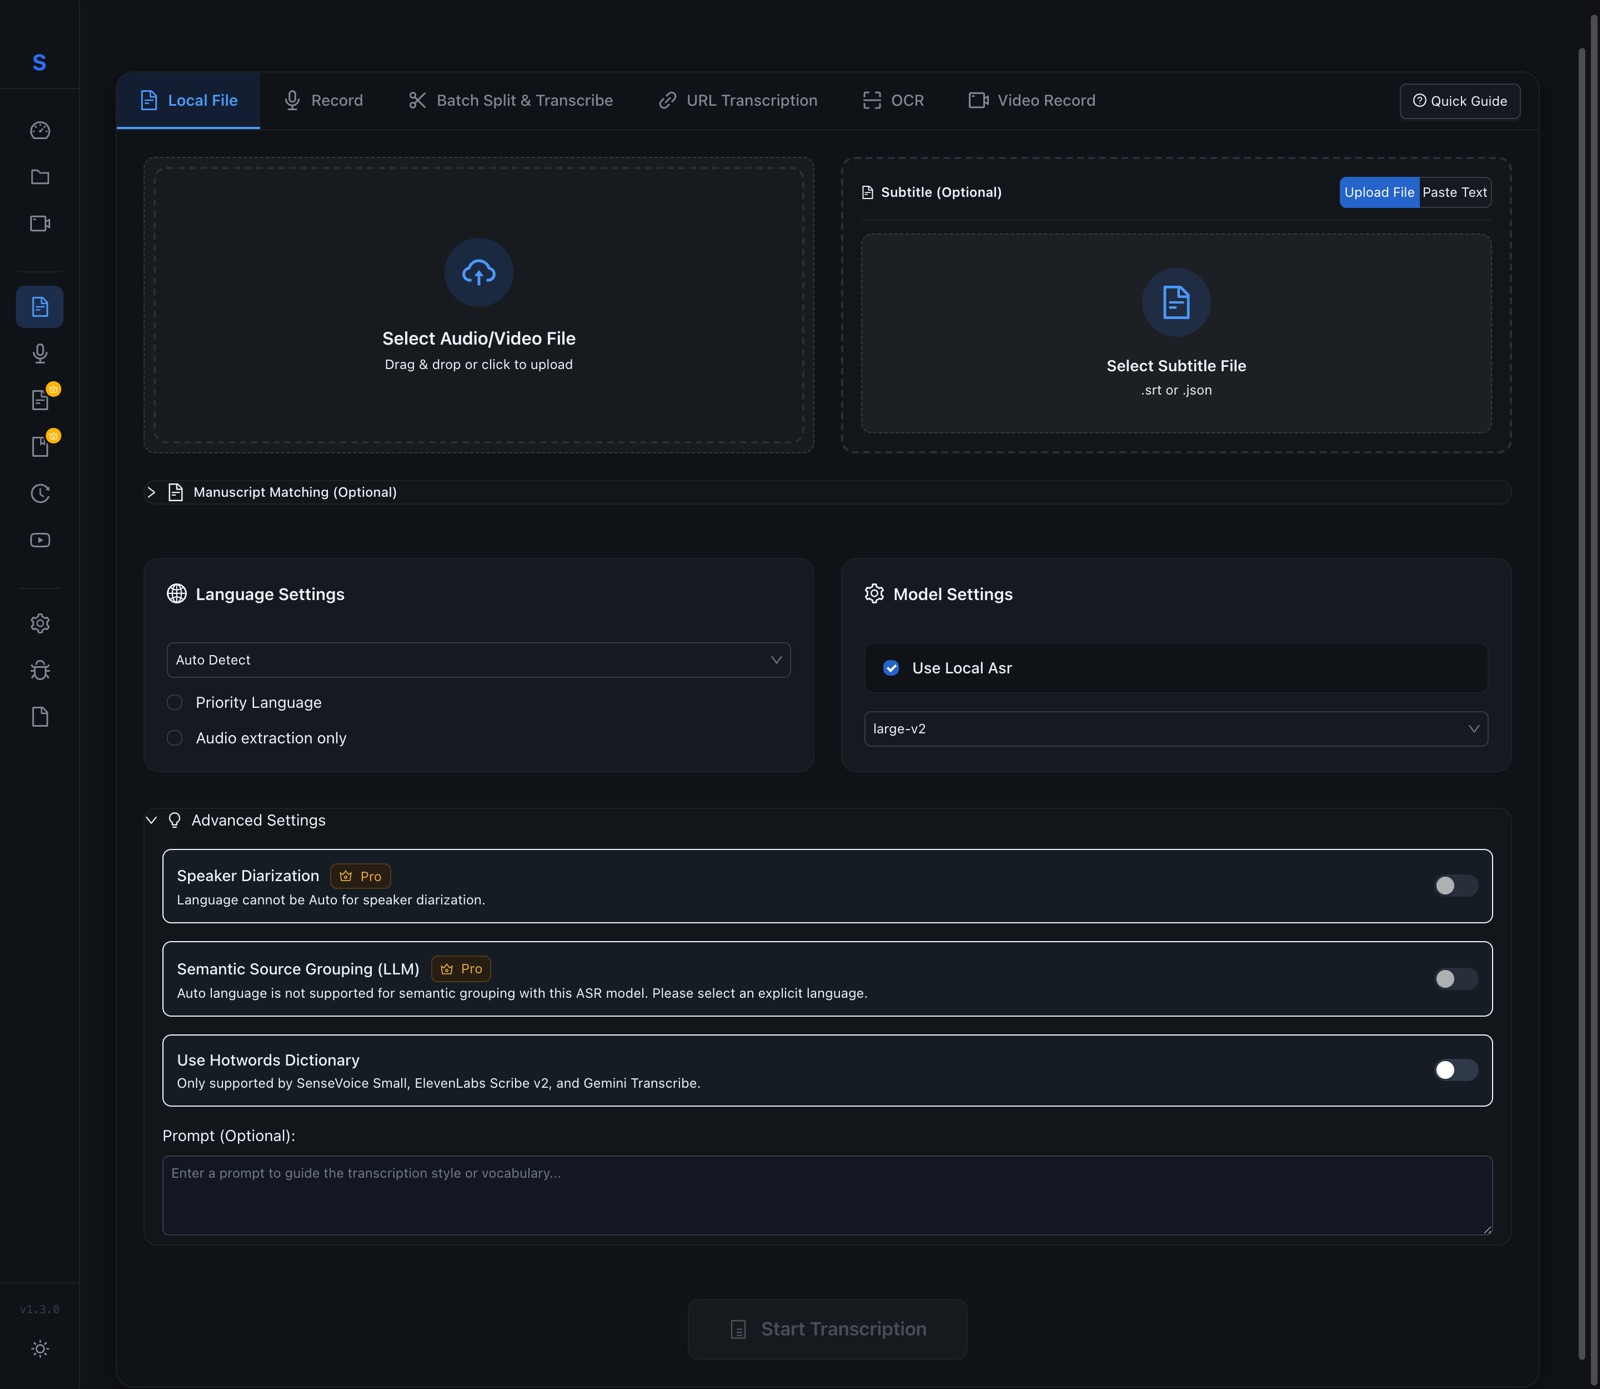
- Speaker Diarization (Pro): when several people are talking, Scribis separates them into "Speaker 1", "Speaker 2" and so on. You need to choose a language first; Auto Detect doesn't work here. Combine it with voiceprints to label people by name automatically.
- Semantic Source Grouping (LLM) (Pro): when it's on, AI decides where subtitles split based on what the sentences mean, so each subtitle is more complete ("LLM" is an AI that can read and understand text). You also need to choose a specific language; Auto Detect won't work.
- Use Hotwords Dictionary: "hotwords" are names, company names and special terms you've added in advance. With this on, the model listens out for them. Add hotwords in Lexicons & Voiceprints › ASR Dictionary first (see Chapter 9). Only these support them: SenseVoice Small (runs on your computer), plus two online services, ElevenLabs Scribe v2 and Gemini Transcribe (these need an API key); with other models, write the special terms in the Prompt below instead.
- Prompt (Optional): background information for the model. Write a sentence or two about what the recording covers, and it's better at recognizing names and special terms. For example:
- "This is a product meeting about Scribis, Gemini and Kubernetes."
- "Use American English spelling."
3.5 Already have subtitles or a script?
- Subtitle (Optional): if you already have a
.srtor.jsonsubtitle file, upload it here to bring it into the editor or use it as a reference. You can also switch to Paste Text and paste it in. - Manuscript Matching (Optional): if you wrote a script beforehand, expand this section and paste it in. Scribis will use the correct wording from your script when lining the text up with the audio.
3.6 Five tips for more accurate subtitles
- Choose the language instead of always using Auto Detect.
- Record somewhere quieter, with the microphone close to the speaker.
- Lots of names and jargon? Put them in the Prompt, or add them as hotwords in the ASR Dictionary.
- Try a different model: the same recording can come out very differently with different models.
- Fix mistakes with AI afterwards: the "Optimize" step in Chapter 7 finds words that may have been misheard and asks you to confirm.
⏱️ Free plan limit: each file can be up to 30 minutes long. Pro has no length limit.
3.7 The other five tabs
Record: record straight into Scribis
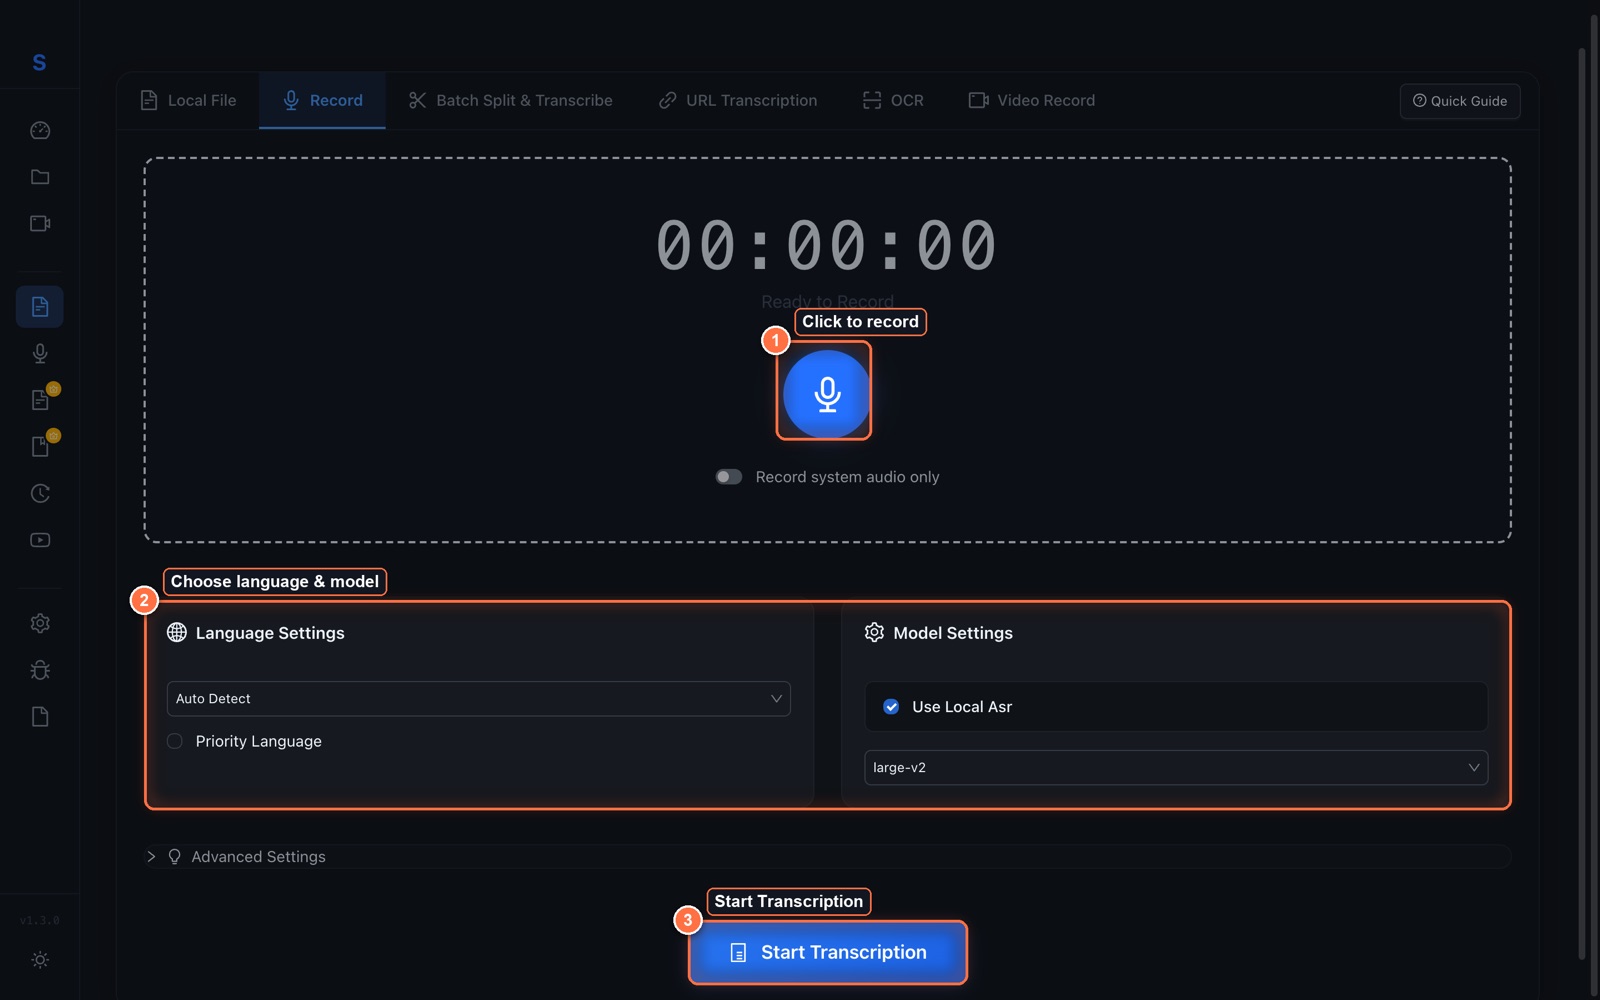
- Click the blue microphone in the middle to start recording. While recording you'll see a pause button (grey) and a stop button (red square).
- After you stop, the screen shows "Recording saved" and the file name, which means the recording is safe. The trash icon next to it throws the recording away so you can record again.
- Choose the language and model, then click Start Transcription. Recording does not turn into text by itself; you must click this button.
- When it's done, the subtitle editor opens.
- Record system audio only: records the sound your computer is playing (for example an online meeting). Note: Include Microphone in Settings › Audio Capture is on by default, so your own voice is recorded too. To record only other people, turn it off there. On a Mac this needs the Screen & System Audio Recording permission: Apple menu › System Settings › Privacy & Security › Screen & System Audio Recording, then turn on Scribis (you may need to reopen Scribis).
- On the Free plan each recording can be up to 10 minutes; it stops automatically when time is up.
- Starting a new recording clears the previous one, so transcribe it first.
💡 Want to see subtitles while you record? Use the Record page in the left menu or the Mini Recorder instead (Chapter 5).
Batch Split & Transcribe: cut a long file into parts
Good for 2–3 hour lectures or meeting recordings (this tab works on Free; the Batch Transcribe page in the sidebar is Pro): Scribis cuts the file in the "gaps where nobody is talking", and each part becomes a separate file in the Media Library, so you can edit them one by one.
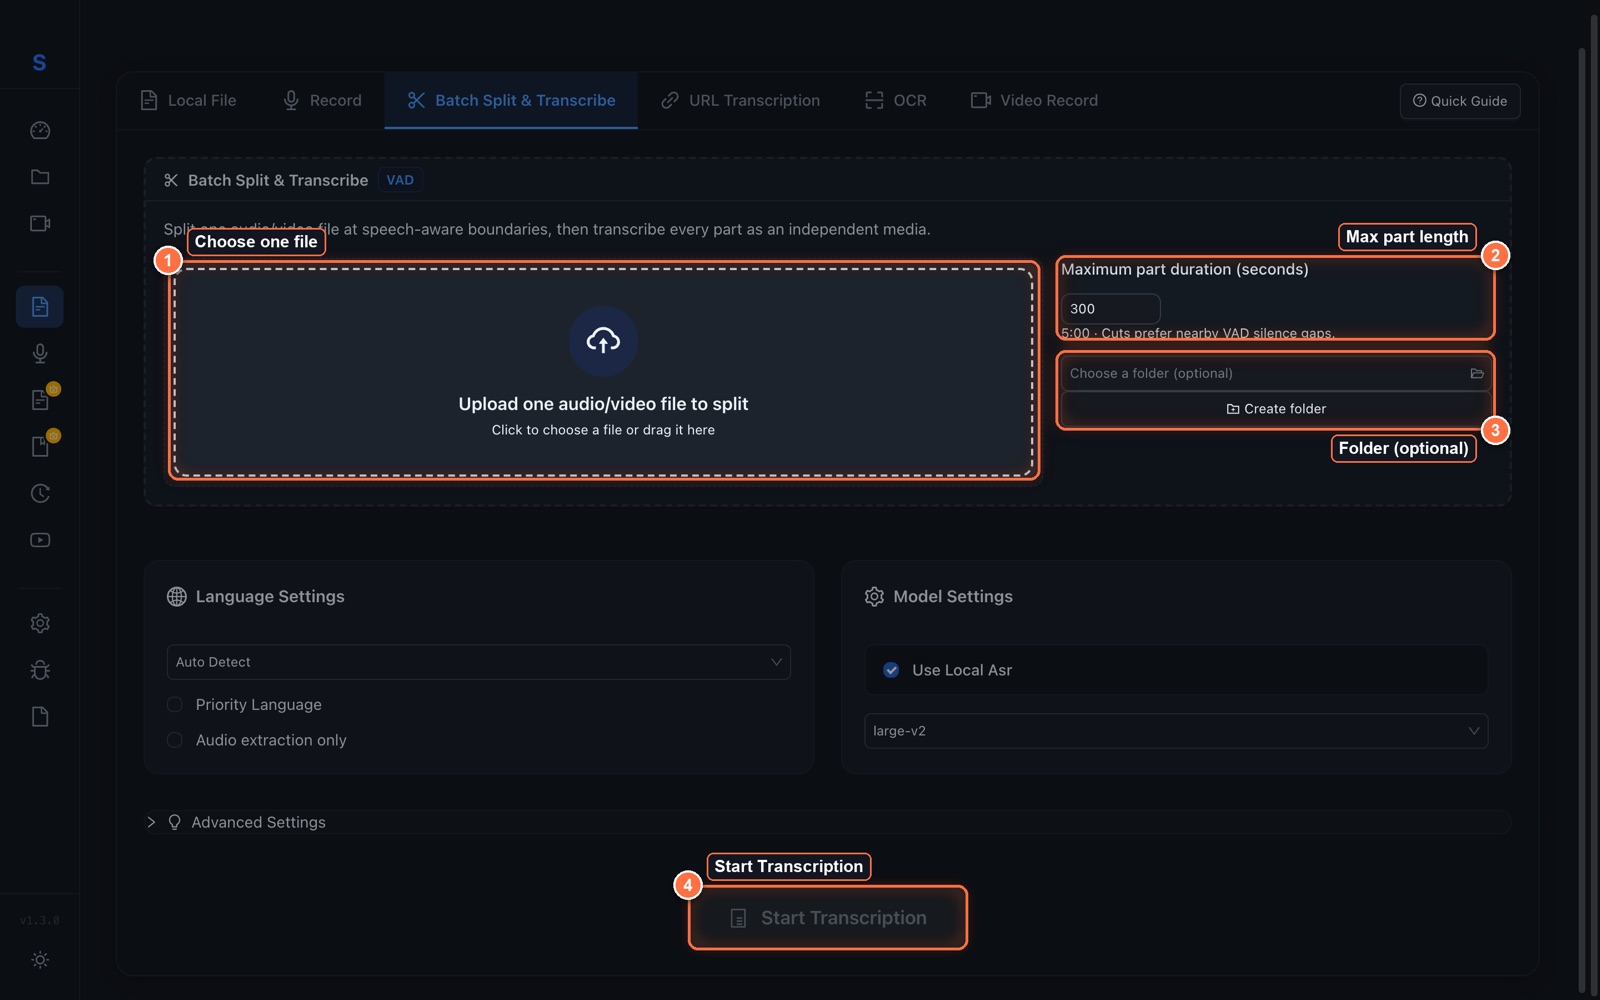
- Pick a file under Upload one audio/video file to split.
- Maximum part duration (seconds): how long each part can be at most. The box is in seconds: the default is 300 (5 minutes), and you can enter 10 to 3600 (60 minutes).
- (Optional) Choose a folder (optional), or click Create folder to make a new one. All the parts go into it.
- Choose the language and model, then click Start Transcription.
- When it's done, the parts are listed under Created media. Only the first part opens in the subtitle editor automatically; open the others from the Media Library.
- This tab doesn't label speakers (Speaker Diarization is ignored even if you turn it on).
- If one part fails, the whole run stops, but the parts already finished stay in the Media Library.
URL Transcription: paste a link and transcribe
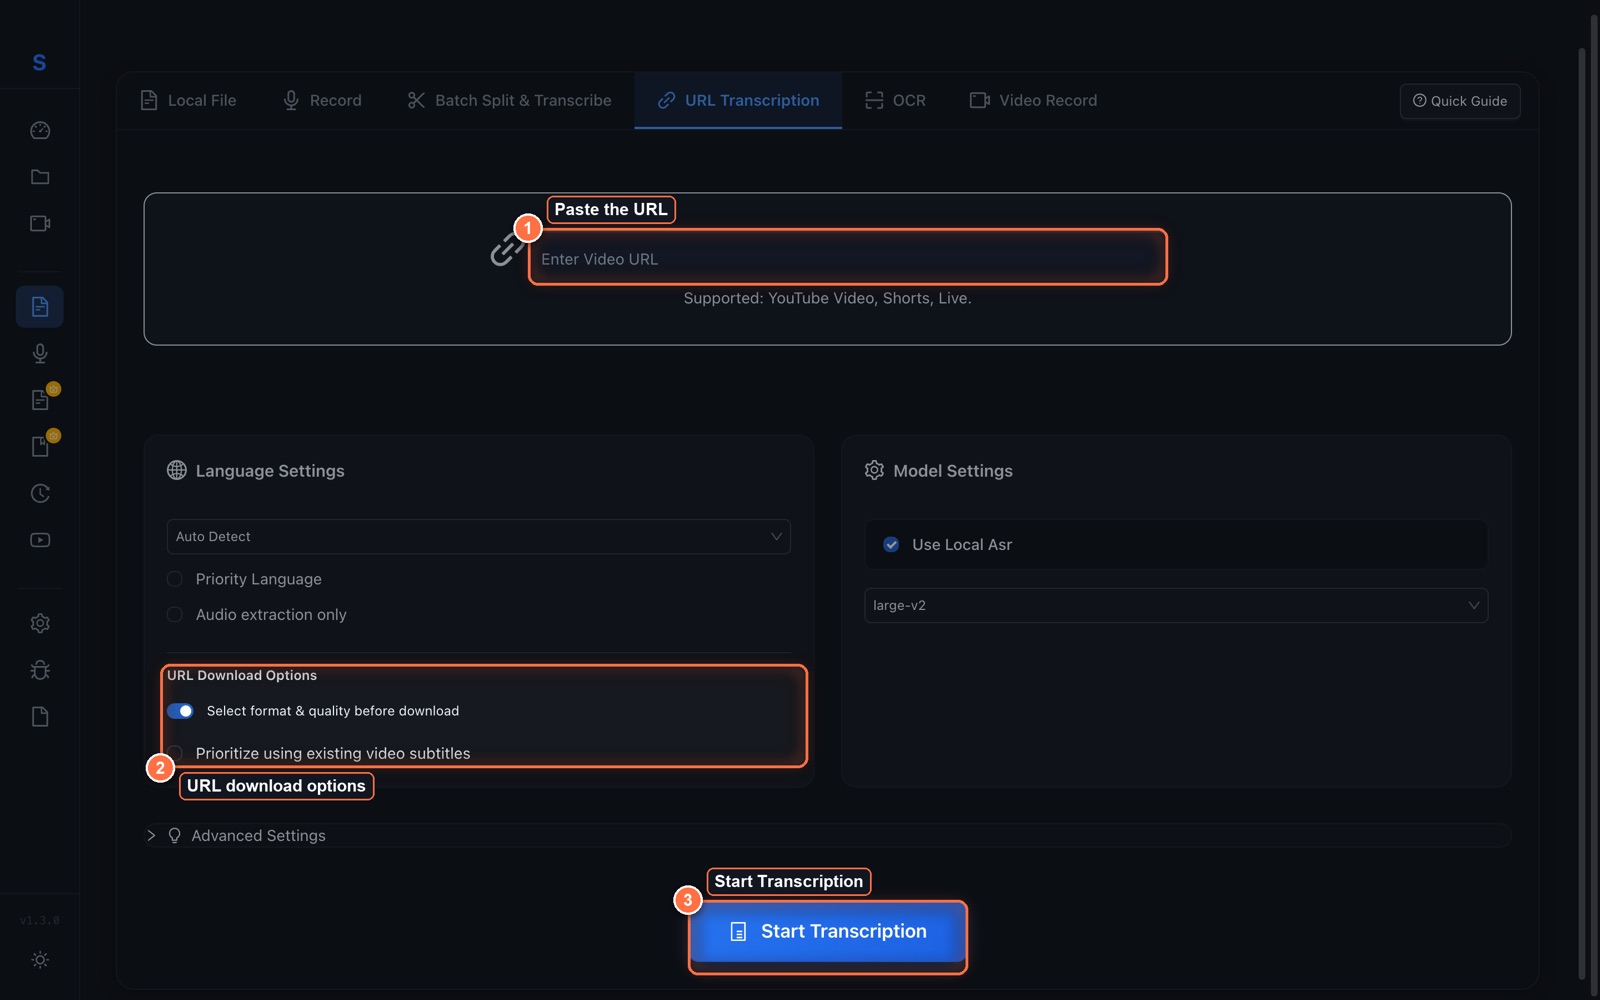
- Paste a YouTube video, Shorts or live-stream link into Enter Video URL.
- Under URL Download Options:
- Select format & quality before download: when this is on, a window asks you to choose the video quality and audio track first; then click Confirm & Transcribe.
- Prioritize using existing video subtitles: if the video already has subtitles, use them instead of recognizing the speech again. (Heavy use may be limited by YouTube.)
- Choose the language and model and click Start Transcription. The subtitle editor opens when it's done.
⚠️ Don't see this tab? The online video feature is off by default. Go to Settings › Online Video, click Get yt-dlp (the downloader) and turn the switch on. The Mac App Store version doesn't have this feature. Only download videos you have the right to use.
OCR: read subtitles that are printed on the picture
OCR is technology that "reads the words in a picture as text". If a video's subtitles are printed onto the picture (there's no subtitle file), OCR can read them and turn them into editable subtitles.
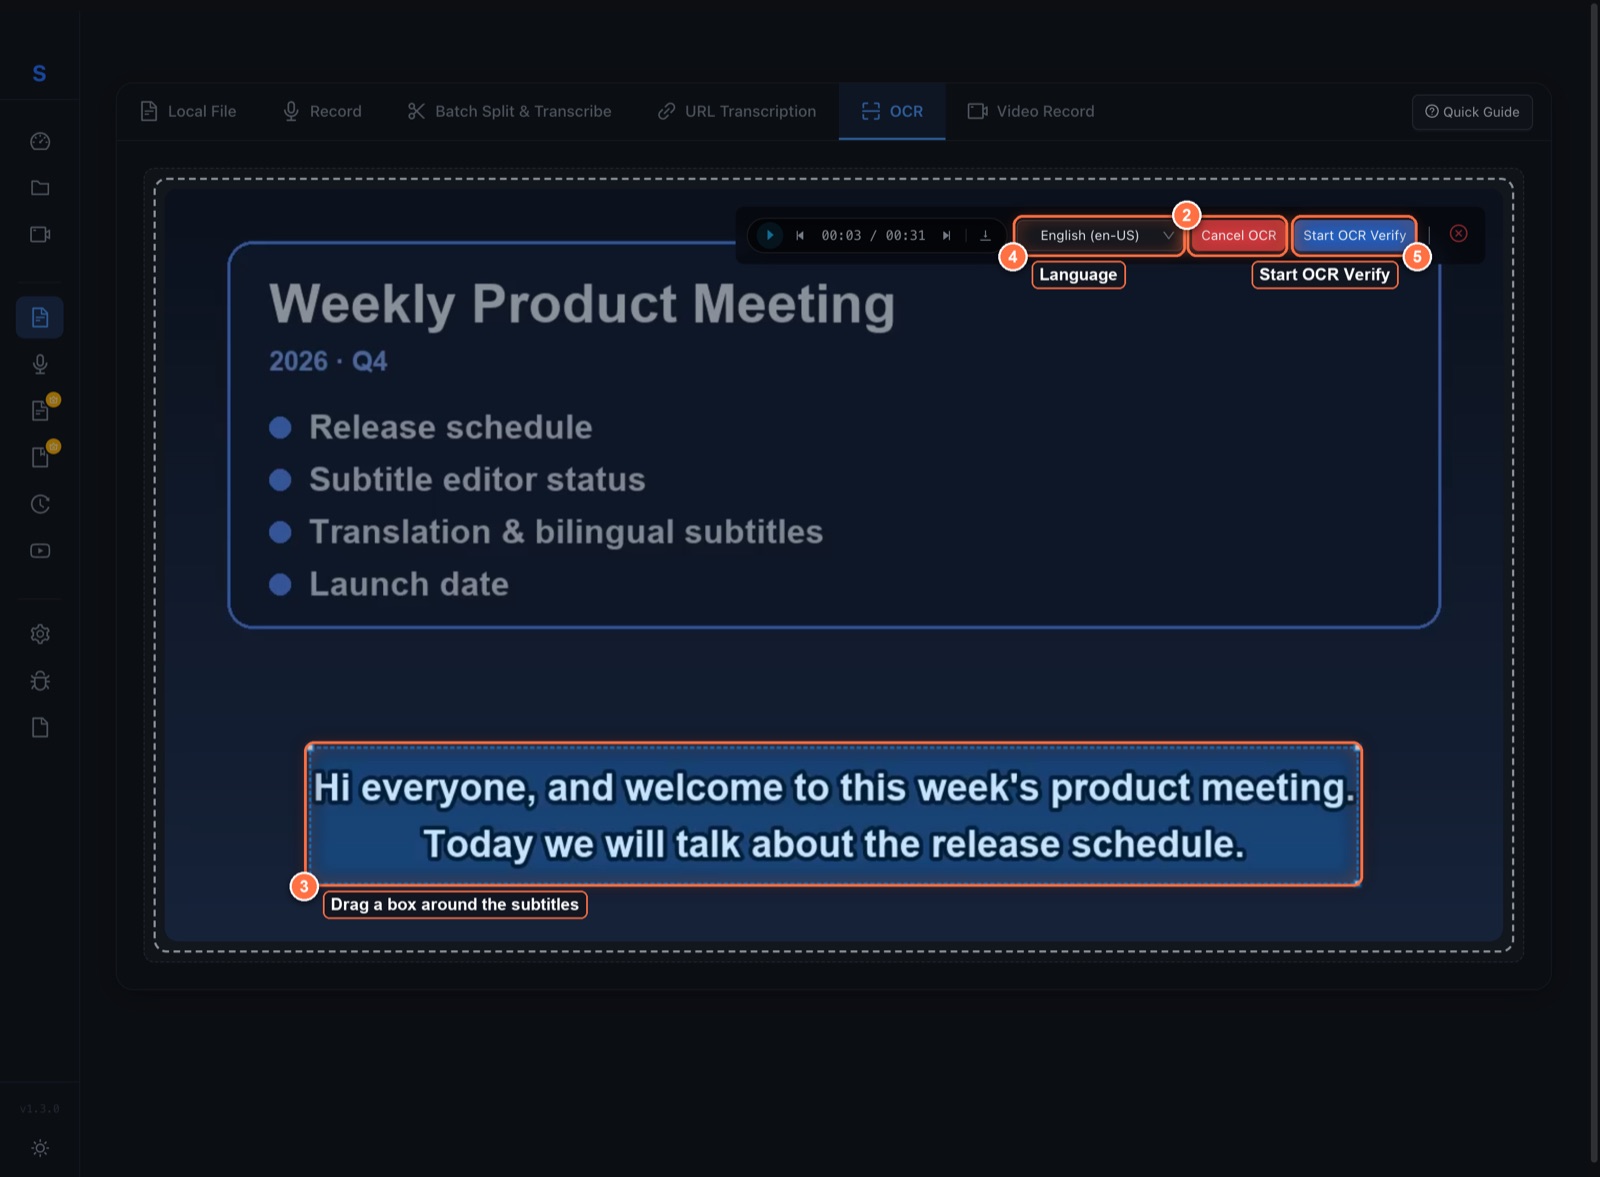
- Choose a video file (
.mp4,.mov,.mkvand so on). - Click OCR Select at the top right.
- Drag a box on the video with your mouse around where the subtitles appear (usually near the bottom).
- Choose the subtitle language (on Windows you can also choose the recognition engine).
- Click Start OCR Verify to start reading the words on the picture. When it's done, the subtitle editor opens and shows the subtitles it read:
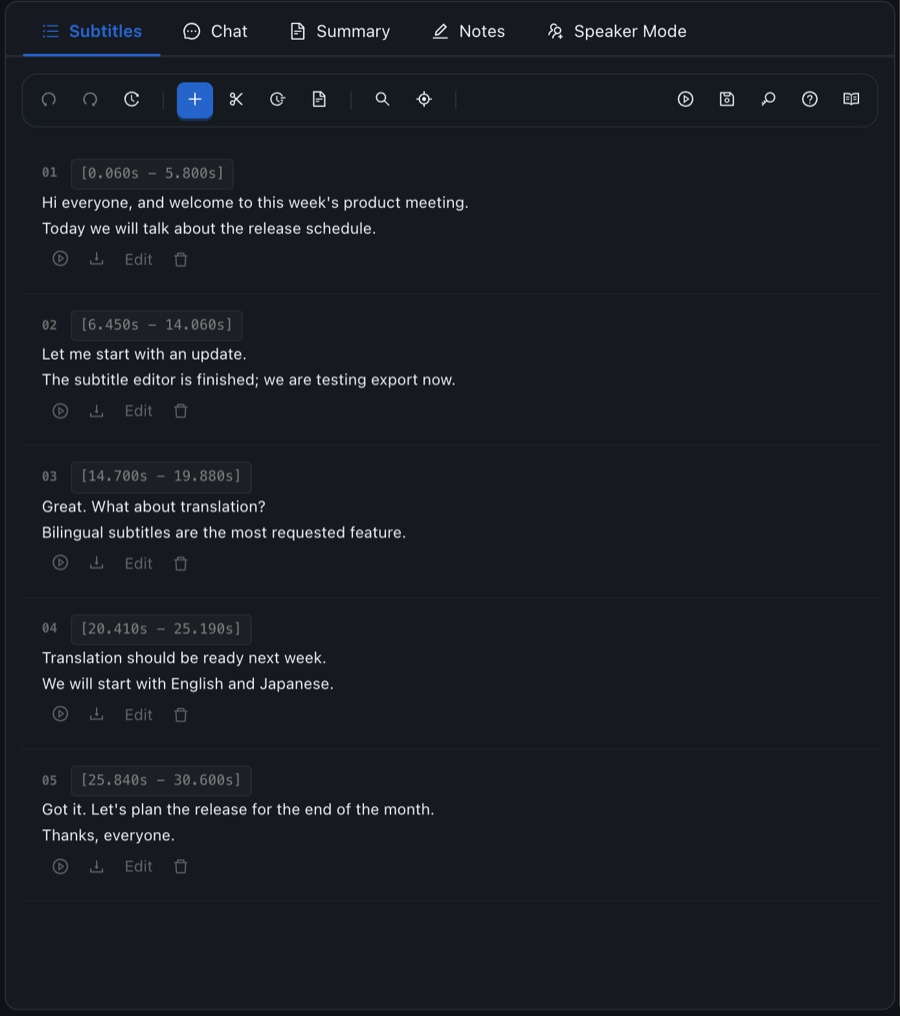
💡 OCR can occasionally misread or miss a character or two, so take a quick look through the result before you export it.
- On a Mac this uses the system's built-in recognition, so nothing needs downloading. On Windows you'll be asked to download a recognition model (about 21 MB) the first time.
- OCR only reads the parts where someone is speaking (Scribis first uses the sound to find where people speak, then reads the picture at those moments). If the video only has music or no voices, you'll see "No speech segments found".
- On the Free plan, videos up to 30 minutes can be processed.
Video Record: record a voice-over while you watch
Good for adding narration to a video, explaining something out loud, or making subtitles quickly by speaking them.
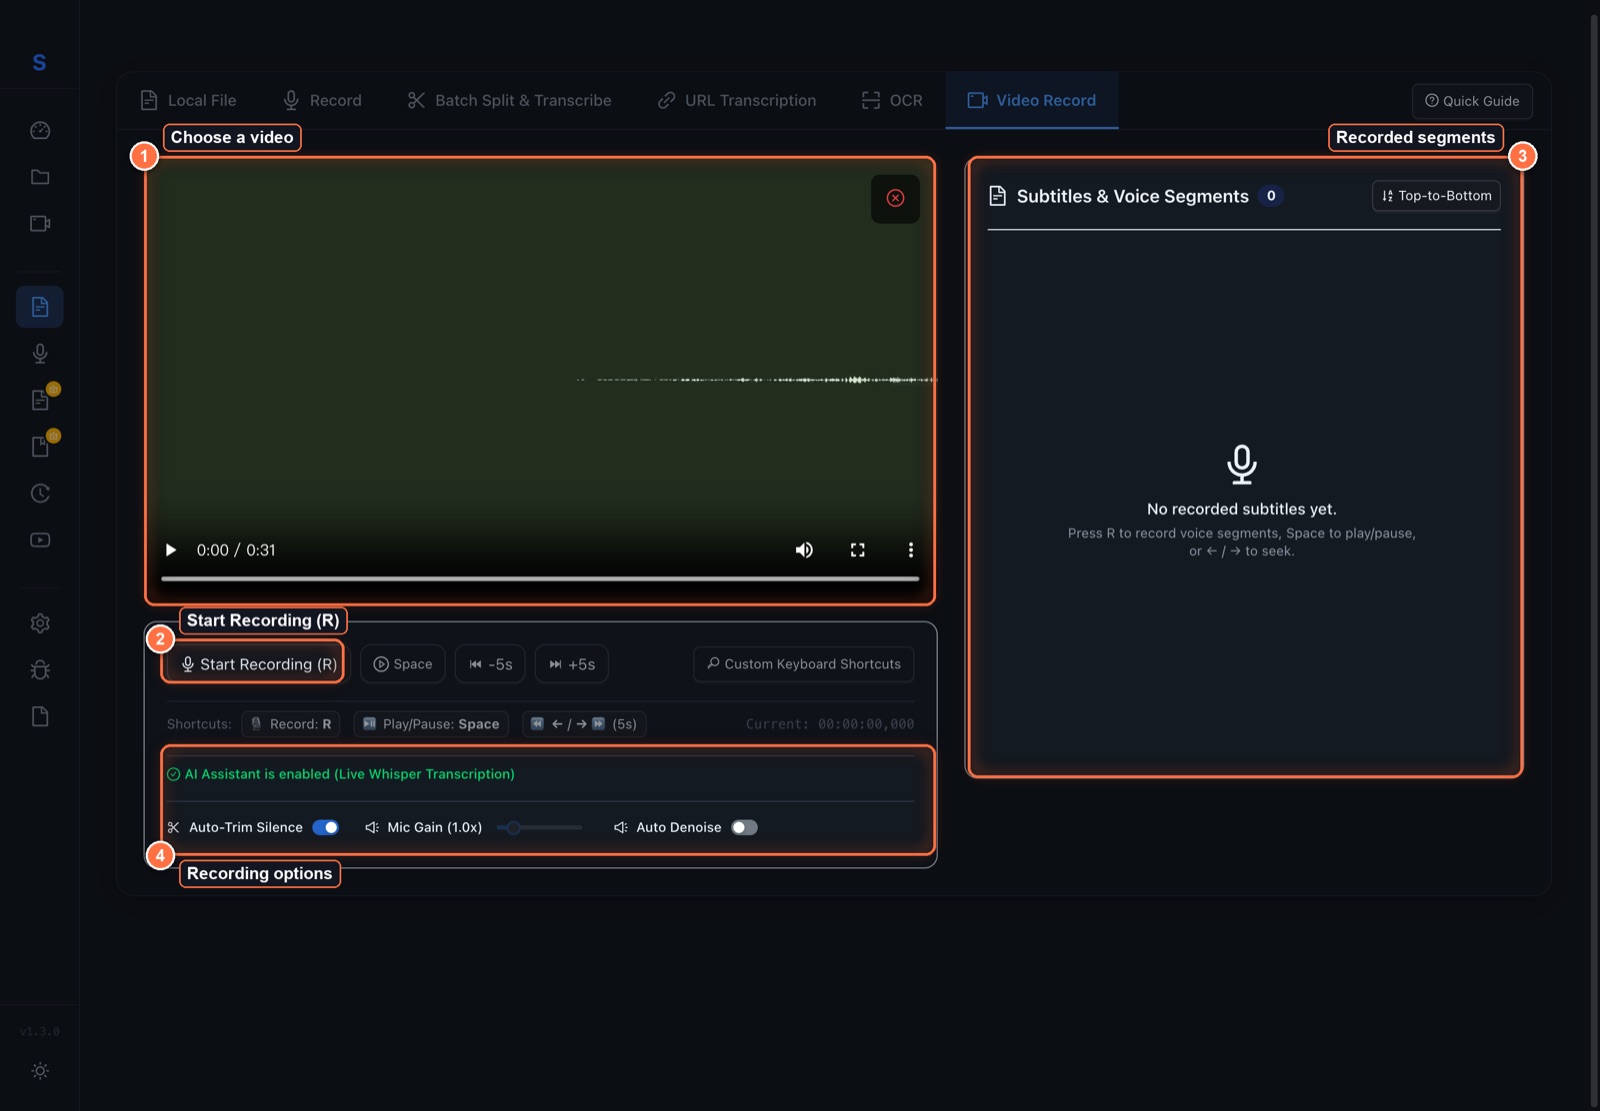
- Choose a video file.
- Click Start Recording (R) (or press
Ron the keyboard). The video starts playing and you talk as you watch. - Press
Ragain (or the space bar) to stop. A new voice segment appears on the right. - Repeat until every part is recorded. For each segment you can change the start and end time, listen again, delete it, or edit its text.
- When you're done:
- Click SRT to download a subtitle file; or
- Click Merge Dubbing with Video: your recording replaces the video's original sound (the picture stays the same, and gaps between recordings become silent), then the subtitle editor opens.
- When the line below says AI Assistant is enabled (Live Whisper Transcription), what you say is turned into text automatically. If it says it's not enabled, the segments only have sound and no text, and you'll need to type it yourself (turn it on in Settings › Assistant).
- Auto-Trim Silence (removes the silent bits before and after each segment), Mic Gain (turns your voice up if it's too quiet) and Auto Denoise (removes background noise; download the model first in Settings › Models › Audio Enhancement) make the recording cleaner.
- ⚠️ Recorded segments are temporary: closing the video or switching tabs deletes them, so download the SRT or merge first.